Tag: startups

  • Rethinking University Founder Education: Beyond Business Plans to Real-World Building

    Rethinking University Founder Education: Beyond Business Plans to Real-World Building

    Rethinking Entrepreneurship in Higher Education: 7 Ways Universities Must Evolve Now to Meet the Change

    When Paul Graham, co-founder of Y Combinator, wrote an essay on how universities should prepare founders, it sparked a debate that cuts to the heart of modern higher education. The traditional entrepreneurship course where students write business plans and pitch to mock investors does little to create the resilience, technical skill, and customer obsession that define successful startup founders. Graham’s argument is simple: if universities want to produce founders, they must shift from teaching about entrepreneurship to enabling actual building.

    The Problem with Traditional Entrepreneurship Education

    Most university entrepreneurship programs are housed in business schools, focusing on writing business plans, financial modeling, and management theory. These skills are useful for running a company, but they are not the core of founding one. A founder’s primary job is to create something people want, a process that involves rapid iteration, direct customer feedback, and technical execution none of which can be learned from a case study.

    Consider the typical capstone project: students form teams, write a 50-page plan, and present to a panel of judges. In the real world, the plan is obsolete the moment it meets a customer. The lean startup methodology, popularized by Eric Ries, emphasizes building a minimum viable product (MVP) and testing it with real users. Universities that cling to the old model are teaching students to be corporate managers, not founders.

    The Y Combinator Model: Learning by Doing

    Graham’s perspective is shaped by Y Combinator, the accelerator that has funded over 3,000 startups, including Airbnb, Dropbox, and Stripe. YC’s approach is stark: founders apply with an idea, get accepted into a cohort, and spend three months building their product with weekly office hours from seasoned mentors. The focus is entirely on making something people want, not on writing plans. Demo Day, where founders pitch to investors, is the culmination—but the real education happens in the daily grind of building.

    Universities can adapt this model. Instead of a semester-long business plan, imagine a course where students must launch a real product to real users. They would need to code, design, market, and iterate—all with the safety net of university resources. The grading would be based on traction (users, revenue, engagement) rather than a paper. This is not a hypothetical; some universities already do this. Stanford’s d.school offers project-based courses, and MIT’s Sandbox program funds student startups. But these are often extracurricular, not integrated into the core curriculum.

    Identifying Founder Traits: Selection Over Instruction

    One of Graham’s most provocative suggestions is that universities should focus on identifying students with founder potential, rather than trying to teach everyone to be a founder. This is a selection problem, not an education problem. Successful founders tend to share traits: a bias toward action, comfort with ambiguity, resilience in the face of rejection, and a deep understanding of a specific problem. Universities can spot these traits through student projects, competitions, and even psychological assessments.

    YC itself is a selection machine. It receives thousands of applications for each cohort and accepts less than 2%. The interview process is intense, focusing on the founders’ determination and clarity, not just the idea. Universities could do the same: create competitive programs that require students to demonstrate their skills before gaining access to resources. This would be a radical departure from the open-enrollment model, but it would align incentives—students would work harder to earn a spot, and the program would attract the most driven individuals.

    Normalizing Failure: The Missing Lesson

    A major obstacle to founder education is the stigma around failure. In universities, failure is punished with bad grades and shame. In the startup world, failure is a stepping stone—most successful founders have failed multiple times before hitting their stride. A university that wants to prepare founders must create a culture where failure is not just tolerated but celebrated as a learning opportunity.

    One way is to grade students on the process, not the outcome. If a student launches a product that gets no users, they can still earn top marks by documenting what they learned and how they pivoted. This is the opposite of the perfectionist culture in academia, where a B+ can feel like a catastrophe. By reframing failure as data, universities can help students build the resilience they need to survive the startup grind.

    The Role of Networks: Connecting Students to Real Founders

    Another key component is exposure to working founders. Most university entrepreneurship courses are taught by professors who have never started a company. They can teach theory, but they cannot convey the visceral experience of pitching to a skeptical investor or the loneliness of a 3 a.m. debugging session. Bringing in guest speakers is not enough; students need ongoing mentorship from people who have been in the trenches.

    Universities are uniquely positioned to facilitate this. They have alumni networks full of founders, investors, and operators. A structured mentorship program, where each student founder is paired with a successful alumnus, could provide the guidance that no textbook can offer. Moreover, connecting students with local startups for internships or project collaborations can give them a taste of the real world while still in school.

    The Skeptical View: Should Universities Even Do This?

    Not everyone agrees. Critics argue that universities’ core mission is education, not startup creation. Funding founder programs could divert resources from humanities and basic science. Furthermore, the high failure rate of startups means many students will not succeed, potentially wasting their time and tuition money. There is also a question of elitism: YC-backed founders are a tiny, privileged fraction; should public universities allocate scarce resources to groom a few potential billionaires?

    These are valid concerns, but they miss a larger point. Founder skills—like resilience, creativity, and problem-solving—are valuable in any career, not just startups. Even if a student never starts a company, learning to build a product and empathize with users will make them a better employee, researcher, or civil servant. Moreover, universities already invest in career services, which prepare students for the corporate ladder. Offering an alternative path for those who want to build something new is a natural extension.

    A Path Forward: Practical Recommendations

    For universities willing to embrace this challenge, here are concrete steps:

    1. Create a founder track within existing majors, not a separate program. Students in engineering, computer science, or even liberal arts should be able to replace a traditional capstone with a startup project.
    2. Fund micro-grants for student experiments. YC gives each startup $500k; universities can give $5k to cover hosting, software, or user testing. The key is to remove financial barriers.
    3. Establish a “founder-in-residence” program. Bring in a successful founder to spend a semester on campus, mentoring students and teaching a hands-on course.
    4. Develop a network of local startups willing to host student interns for credit. This provides real-world experience without the risk of a full-time commitment.
    5. Change the grading rubric for project courses. Emphasize iteration, user feedback, and learning, not just the final product.

    These steps are not radical; they are incremental. But they signal to students that the university values action over theory, and that is the first step toward creating a founder culture.

    Conclusion

    Universities have a choice: continue churning out employees or start preparing founders. The demand is there—students increasingly want to create their own paths. By embracing the principles of learning by doing, selecting for founder traits, normalizing failure, and connecting students with real-world mentors, universities can fulfill a new mission. The future belongs to those who build, and universities can be the launchpad.

    The debate sparked by Paul Graham’s essay is not just about entrepreneurship education; it’s about the purpose of a university in the 21st century. As the cost of starting a company drops and the tools for creation become accessible, the ability to build and launch products is a fundamental skill. Universities that adapt will produce graduates who are not just job-ready but world-ready—ready to shape the future, not just fit into it.

    Summary

    • Traditional entrepreneurship education focuses on business plans, but founders need to build and iterate.
    • The Y Combinator model emphasizes learning by doing, with a focus on making something people want.
    • Universities should select for founder traits rather than trying to teach everyone to be a founder.
    • Normalizing failure is essential; students need to learn from setbacks, not fear them.
    • Connecting students with real founders and local startups provides mentorship that theory cannot.

    FAQ

    Q: Is entrepreneurship education the same as founder preparation?
    A: No. Entrepreneurship education often covers management, finance, and business planning. Founder preparation focuses on the specific skills needed to start a company, like building a product, getting users, and iterating.

    Q: Can universities really teach resilience and a bias toward action?
    A: These traits are more about selection and environment than instruction. Universities can create programs that reward risk-taking and persistence, and select students who already exhibit these qualities.

    Q: What about the risk of students failing and wasting resources?
    A: Failure is a learning opportunity. Universities can change grading to reward the process, not just the outcome, so students gain value even if their startup does not succeed.

    Q: How can universities without huge budgets implement these ideas?
    A: They can start small—partnering with local startups, inviting guest speakers, and offering courses that replace traditional projects with hands-on building. Even modest changes can shift the culture.

    Q: Is it fair to focus resources on a few potential founders?
    A: Founder skills benefit many careers, not just startups. And by creating competitive programs, universities can ensure they are investing in the most motivated students, which is a fair use of resources.
  • How to Invest in Agentic AI: From Big Tech to Bold Startups

    How to Invest in Agentic AI: From Big Tech to Bold Startups

    Imagine software that doesn’t just answer questions but actually gets things done booking your travel, writing code, or negotiating with vendors all on its own. That’s agentic AI, the next big wave in artificial intelligence. For investors, this shift from ‘AI that talks’ to ‘AI that acts’ opens up a fresh set of opportunities, but it also comes with new risks.

    This guide breaks down what agentic AI is, why it’s attracting billions in investment, and the concrete ways you can get exposure from buying shares of tech giants to betting on startups. Whether you’re a seasoned investor or just starting to explore AI, you’ll leave with a clear map of the landscape.

    What Is Agentic AI, Really?

    Agentic AI refers to systems that can autonomously pursue complex goals with minimal human oversight. Unlike generative AI like ChatGPT, which produces content when prompted, agentic AI acts—it can browse the web, write code, book travel, or manage workflows independently. Think of it as the difference between a chef who follows a recipe you give them and a personal assistant who plans the entire meal, shops for ingredients, and cooks it without being asked.

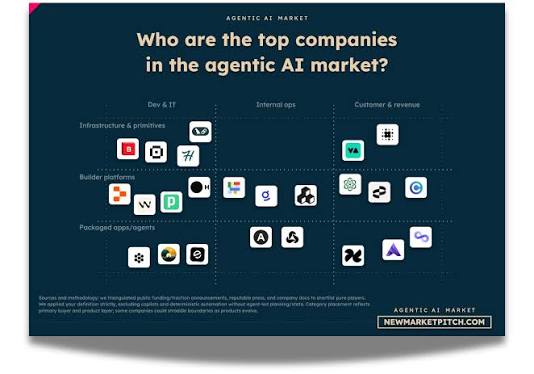
    This technical leap became possible because large language models (LLMs) improved enough to handle multi-step reasoning, use tools, and remember context. As a result, agentic AI is moving from research labs into early commercial products. Big players like OpenAI (with Operator and AgentKit), Anthropic (computer use), Google (Project Mariner), and Microsoft (Copilot agents) are all betting on this future.

    The Market: Big Numbers, Big Hype

    Market forecasts for agentic AI vary widely but are consistently bullish. Some analysts project the market to reach $30–50 billion by 2030, with compound annual growth rates of 40–50%. Others place it higher, at $100+ billion, depending on how broadly you define ‘agentic’ to include infrastructure. Either way, the growth is expected to be explosive.

    Enterprise adoption is a key driver. Gartner predicts that by 2028, 33% of enterprise software will include agentic AI, up from less than 1% in 2024. That’s a massive shift. Venture funding reflects the excitement: agentic AI startups raised over $5 billion in 2024, with companies like Sierra, Decagon, Adept, Imbue, and Harvey attracting significant capital.

    Why Now? The Stars Are Aligning

    Three forces have converged to make agentic AI investable. First, technical maturity: LLMs can now handle the complex reasoning and tool use required for agency. Second, enterprise pain points: businesses are drowning in data but starved for labor, and agents promise to automate knowledge work. Third, the cost curve: inference costs have fallen roughly 10x per year for some models, making agent deployment economically viable.

    Think of it like the early days of the internet. For years, companies spent money on websites that were little more than brochures. Then, as infrastructure matured, e-commerce and software-as-a-service (SaaS) exploded. Agentic AI is at that inflection point—the infrastructure is ready, and the use cases are becoming clear.

    Investment Vehicle 1: Large-Cap Tech Stocks

    The simplest way to invest in agentic AI is through the tech giants that are building or enabling it. These companies have the resources to develop agents, the distribution to deploy them, and the balance sheets to weather setbacks. Key names include:

    • Microsoft – integrating agents into its Copilot suite and Azure cloud
    • Alphabet (Google) – Project Mariner and its Gemini models
    • Amazon – AWS AI services and its investment in Anthropic
    • Meta – open-source Llama models and its massive compute infrastructure
    • Nvidia – the dominant supplier of AI chips, a critical enabler
    • Salesforce – embedding agents into its CRM platform
    • ServiceNow – automating workflows with AI agents

    These are the ‘picks and shovels’ of the agentic gold rush. Even if specific agents fail, these companies will likely benefit from the broader trend.

    Investment Vehicle 2: Pure-Play and Smaller Stocks

    For higher risk and higher potential reward, you can look at smaller companies focused specifically on AI. Names like C3.ai, SoundHound AI, and BigBear.ai are often more volatile but offer direct exposure to the agentic AI theme. However, be cautious: many trade at extreme valuations, sometimes 50–100x revenue, with little profitability. The hype can outpace reality, so due diligence is critical.

    Investment Vehicle 3: Private Markets and Venture Capital

    If you’re an accredited investor, you can invest directly in startups through venture capital funds or angel syndicates. This is where the biggest returns could be, but also the highest risk. Many startups fail, and liquidity can take years. If you’re not accredited, you might still participate through crowdfunding platforms, but tread carefully.

    Investment Vehicle 4: AI-Focused ETFs

    Exchange-traded funds (ETFs) offer a diversified way to invest in AI. Examples include BOTZ (Global X Robotics & Artificial Intelligence), AIQ (Global X Artificial Intelligence & Technology), and IRBO (iShares Robotics and Artificial Intelligence). These hold baskets of AI-related stocks, spreading risk across many companies. They’re a good option if you want exposure without picking individual winners.

    Investment Vehicle 5: Infrastructure Plays

    Don’t forget the infrastructure that makes agentic AI possible. Semiconductors like Nvidia, AMD, and TSMC are in high demand. Cloud providers like AWS, Azure, and GCP provide the compute power. Data center REITs like Equinix and Digital Realty own the physical facilities. These companies benefit from the AI boom regardless of which agents win.

    The Bull Case: Why Invest?

    Proponents argue that agents could automate 20–30% of knowledge work, creating massive enterprise value. Software vendors can shift from per-seat to per-task or per-outcome pricing, potentially increasing revenue per customer. Platforms that aggregate agents—like an ‘app store for agents’—could become dominant infrastructure. Historical precedent suggests that every major tech wave (internet, mobile, cloud) created outsized returns for early investors in the right picks.

    The Bear Case: Risks to Watch

    Skeptics point out that the gap between demo videos and production-ready reliability remains wide. Many ‘agents’ are still brittle, error-prone, and require human supervision. Valuation concerns are real: some pure-play AI stocks trade at astronomical multiples. LLMs themselves are becoming commoditized; the moat may be in distribution, data, or workflow integration, not the model itself. And security failures—like an agent making unauthorized purchases or leaking data—could erode trust.

    Regulatory and Policy Risks

    The regulatory landscape is still evolving. The EU AI Act classifies AI systems by risk, and agentic systems may fall under ‘high-risk’ categories, increasing compliance costs. The US approach is lighter-touch so far, with executive orders and agency guidance rather than comprehensive legislation. California and New York have proposed AI safety bills that could affect deployment. A key open question is liability: when an autonomous agent causes harm, who’s responsible—the maker or the user?

    How to Start Investing

    1. Educate yourself: Follow industry publications, read earnings reports, and understand the technology’s capabilities and limitations.
    2. Diversify: Don’t put all your money in one stock or sector. Use ETFs for broad exposure and individual stocks for targeted bets.
    3. Assess your risk tolerance: Pure-play stocks are volatile; large-cap tech is more stable; private markets are illiquid.
    4. Think long-term: Agentic AI is still in its early stages. Be prepared for ups and downs.
    5. Consult a financial advisor: Especially if you’re considering private markets or complex strategies.

    The Bottom Line

    Agentic AI represents a significant investment opportunity, but it’s not without risks. By understanding the technology, the market, and the various investment vehicles, you can position yourself to benefit from this emerging wave. Whether you choose the safety of large-cap tech, the thrill of startups, or the diversification of ETFs, the key is to stay informed and invest wisely.

    Agentic AI is more than a buzzword—it’s a technological shift with real investment potential. From mega-cap tech to nimble startups, there are countless ways to participate. But as with any wave, the key is to stay grounded. Do your research, diversify your holdings, and keep an eye on both the opportunities and the risks. The future of AI isn’t just about generating text; it’s about getting things done. And for investors, that’s a story worth tuning into.

    Summary

    • Agentic AI systems act autonomously to complete multi-step tasks, unlike generative AI that only produces content.
    • The market is projected to reach $30–100+ billion by 2030, with enterprise adoption expected to jump from under 1% to 33% by 2028.
    • Investment options include large-cap tech stocks (Microsoft, Google, Nvidia), pure-play AI stocks (C3.ai, SoundHound), private startups, AI-focused ETFs, and infrastructure plays.
    • Bullish factors: productivity gains, recurring revenue models, network effects; bearish factors: overhype, high valuations, commoditization, security risks.
    • Regulatory risks vary by region, with the EU AI Act potentially classifying agentic systems as high-risk, and liability questions still unresolved.

    FAQ

    Q: What is the difference between generative AI and agentic AI?
    A: Generative AI produces content in response to prompts (like ChatGPT writing an essay). Agentic AI goes further—it can plan, use tools, and execute tasks autonomously, such as booking a flight or managing a calendar.

    Q: Can I invest in agentic AI without picking individual stocks?
    A: Yes. AI-focused ETFs like BOTZ, AIQ, and IRBO offer diversified exposure to a basket of AI-related companies, reducing single-stock risk.

    Q: Are agentic AI investments risky?
    A: Yes. The technology is still evolving, and many agents are not yet production-ready. Some pure-play stocks trade at high valuations, and private startups carry high failure risk.

    Q: What are the most important companies in agentic AI?
    A: Major players include Microsoft, Google, Amazon, and Nvidia, as well as startups like OpenAI, Anthropic, and Sierra. These companies are leading in research, development, and infrastructure.

    Q: How can I get exposure to agentic AI as a non-accredited investor?
    A: You can invest in public equities, ETFs, or real estate investment trusts (REITs) that own data centers. Crowdfunding platforms may also offer opportunities, but they carry higher risks.

  • 3 Mental Models That Will Change How You Make Decisions

    3 Mental Models That Will Change How You Make Decisions

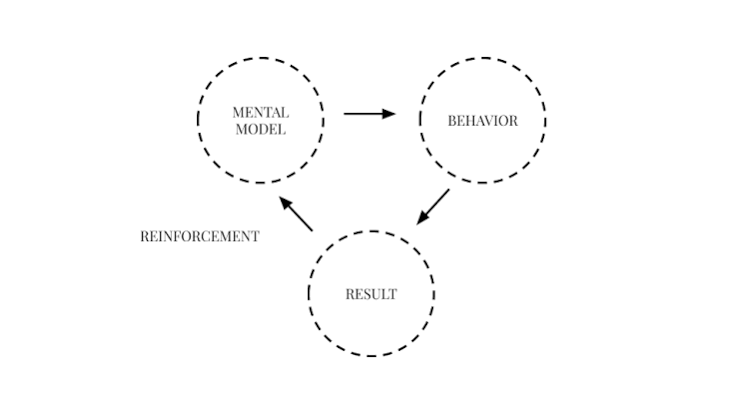
    Every decision you make—from choosing a career to investing in a startup—relies on mental models: simplified frameworks that help you interpret the world and predict outcomes. Charlie Munger, Warren Buffett’s partner, built his legendary investing career on a ‘latticework’ of these models, and modern thinkers like Elon Musk have used them to revolutionize industries. But with dozens of models to choose from, which ones matter most?

    After cross-referencing the most authoritative sources—Munger’s speeches, Farnam Street’s curriculum, and decision-making literature—three models consistently rise to the top: Inversion, First Principles Thinking, and The Map Is Not the Territory. These aren’t just abstract concepts; they’re practical tools that can help you avoid catastrophic mistakes, innovate where others fail, and stay humble in the face of uncertainty. Here’s how they work and why they matter.

    Why Mental Models Matter

    Before diving into the models, it’s worth understanding why they’re so powerful. Human brains are wired for shortcuts, but those shortcuts often lead to bias and error. Mental models act as a corrective lens, forcing you to see problems from multiple angles. Munger once said that having about 80–100 models from various disciplines is enough for ‘worldly wisdom.’ But if you’re just starting out, these three are the foundation.

    Inversion: The Power of Avoiding Stupidity

    The mathematician Carl Jacobi famously advised, ‘Invert, always invert.’ Charlie Munger adopted this as a core principle, and it’s easy to see why. Instead of asking, ‘How do I succeed?’ you ask, ‘What would guarantee failure?’ Then you systematically avoid those things.

    How It Works

    Inversion exploits the asymmetry of risk: avoiding a disaster is often easier than achieving a triumph. For example, if you’re launching a product, instead of asking, ‘What will make it successful?’ ask, ‘What would make it fail?’ The answers—poor marketing, bad pricing, ignoring customer feedback—become a checklist of what not to do.

    Real-World Application

    Investors use inversion to screen out bad bets. Munger once said that he and Buffett spend most of their time ‘thinking about what could kill a business.’ By identifying fatal flaws early, they avoid losses that would be hard to recover from. In engineering, inversion is standard practice: ‘What would cause this bridge to collapse?’ ensures every failure point is addressed.

    First Principles Thinking: Breaking Down to Build Up

    First principles thinking has roots in Aristotelian philosophy, but Elon Musk brought it into the mainstream. Instead of reasoning by analogy—copying what others do—you break a problem down to its most fundamental truths and reason upward from there.

    How It Works

    Musk’s approach is simple: ‘Boil things down to physics.’ When he started SpaceX, he asked, ‘What does a rocket actually cost?’ The raw materials were about 2% of the price. By starting from that truth, he realized he could build rockets for a fraction of the cost, disrupting the entire aerospace industry.

    Why It’s Powerful

    Reasoning by analogy is what Munger called ‘the worst kind of thinking.’ It leads to incremental improvements, not breakthroughs. First principles, on the other hand, lets you question assumptions. When everyone else sees ‘the way things are,’ you see ‘the way things could be.’

    The Map Is Not the Territory: Stay Humble, Stay Flexible

    This model was coined by Alfred Korzybski in 1931 and later adopted by Munger. It reminds us that our mental models are approximations of reality, not reality itself. The map is always incomplete, and sometimes it’s just wrong.

    How It Works

    Think of a city map: it helps you navigate, but it doesn’t show every pothole or construction detour. Similarly, your business plan, your investment thesis, your understanding of a friend—all are maps. When reality doesn’t match your map, it’s easy to get frustrated. But the model teaches you to update your map instead of ignoring reality.

    Why It’s the Meta-Model

    This is the model that keeps all other models honest. Inversion and first principles are powerful, but they can lead to overconfidence if you forget they’re just tools. The Map Is Not the Territory reminds you to hold your beliefs loosely. As Munger put it, you should be ‘learning all the time’ and rarely be ‘sure of anything.’

    Putting It All Together

    These three models work best in combination. Inversion helps you avoid mistakes; first principles helps you find new solutions; and the map model helps you stay adaptable when reality shifts. For example, a startup founder might use first principles to design a new product, inversion to identify potential pitfalls, and the map model to pivot when customer feedback contradicts initial assumptions.

    Practical Tips for Daily Use

    • Start an ‘inversion journal’: For any important decision, write down three ways it could go wrong, then plan to avoid them.
    • Practice first principles on small problems: Pick a routine task and ask, ‘What am I assuming that might not be true?’
    • Label your maps: When you form an opinion, write it down with a date. When new information comes in, update it—and note the change. This keeps you honest.

    Why These Three, Not Others?

    There are dozens of mental models—from supply and demand to game theory—but these three stand out because they’re foundational. Inversion addresses the asymmetry of risk, first principles addresses the limits of analogy, and the map model addresses the limits of all models. Together, they form a complete toolkit for clear thinking.

    Mental models aren’t just intellectual exercises; they’re practical survival tools. By mastering inversion, first principles, and the map-is-not-the-territory, you can think more clearly, decide more wisely, and avoid the pitfalls that trap most people. Start small: apply inversion to a decision this week, use first principles on a problem you’ve been putting off, and remind yourself that your maps are never perfect. The results will speak for themselves.

    Summary

    • Inversion flips the question from ‘How to succeed?’ to ‘What would cause failure?’—making it easier to avoid disasters.
    • First Principles Thinking breaks problems down to fundamental truths, enabling true innovation rather than incremental change.
    • The Map Is Not the Territory reminds us that all models are imperfect, keeping us humble and adaptable.
    • These three models are the most frequently cited across authoritative sources like Charlie Munger and Farnam Street.
    • Combining them gives you a robust framework for decision-making in any domain.

    FAQ

    Q: What are mental models?
    A: Mental models are simplified frameworks for understanding how the world works. They help you interpret information, predict outcomes, and make better decisions by providing a structure for thinking.

    Q: Who created these three mental models?
    A: Inversion is attributed to mathematician Carl Jacobi and popularized by Charlie Munger. First principles dates back to Aristotle but was modernized by Elon Musk. The Map Is Not the Territory was coined by Alfred Korzybski in 1931 and adopted by Munger.

    Q: How can I use inversion in my daily life?
    A: For any goal, ask ‘What would guarantee failure?’ and then avoid those things. For example, if you want to save money, list what would ruin your savings (impulse buying, high-interest debt) and avoid them.

    Q: Is first principles thinking only for entrepreneurs?
    A: No. You can apply it to any problem, like career planning. Instead of following the traditional path, ask ‘What do I need to be happy and fulfilled?’ and build from there.

    Q: How do I know when my ‘map’ is wrong?
    A: When reality contradicts your expectations, that’s a sign. Instead of getting defensive, ask ‘What does this tell me about my model?’ and update it accordingly.

  • The AI Bubble Is Popping; We Just Don’t Know It Yet

    The AI Bubble Is Popping; We Just Don’t Know It Yet

    In late 2022, ChatGPT burst onto the scene, igniting a global frenzy. Venture capital poured into AI startups, tech giants raced to build massive data centers, and the stock market rewarded anything with an ‘AI’ label. But beneath the surface, a different story is unfolding. The AI bubble is not bursting with a bang; it’s leaking slowly, and most of us haven’t noticed yet.

    This article explores the signs that the AI boom is deflating, from overvalued companies and soaring costs to enterprise fatigue and open-source competition. We’ll look at why the bubble is deflating quietly, what it means for the industry, and how we can navigate the coming correction. By understanding the dynamics at play, we can separate hype from reality and make informed decisions about AI’s future.

    The Hype Cycle and the Quiet Leak

    Every major technological revolution follows a pattern: excitement, overinvestment, disillusionment, and eventual maturity. The AI boom is no different. The initial euphoria, sparked by ChatGPT’s release, led to a massive influx of capital. Companies with little more than a chatbot prototype received billion-dollar valuations. But the hype is cooling. The bubble is not popping with a dramatic crash; it’s leaking slowly, like a tire with a small puncture. Layoffs, down-rounds, and quiet shutdowns are happening now, but the headline indices—like the NASDAQ—are still buoyed by a few mega-cap stocks, masking the underlying weakness.

    The Valuation-Reality Gap

    One of the clearest signs of a bubble is when valuations far outstrip actual revenue. Many AI startups and public companies trade at multiples that defy traditional financial logic. For example, OpenAI and Anthropic have valuations in the tens of billions, yet their revenue is a fraction of that. Nvidia, the chipmaker, has seen its stock soar, but its success is tied to a spending spree that may not last. The gap between what companies are worth and what they actually earn is a classic bubble indicator. When the music stops, those with weak fundamentals will suffer the most.

    The Costly Reality of AI

    Training a frontier AI model costs hundreds of millions, sometimes billions, of dollars. And the costs don’t stop there. Running these models—known as inference—requires massive computing power, and the electricity to power it. For many AI companies, the cost of serving each user exceeds the subscription price they charge. This is unsustainable. As costs remain high and revenue growth slows, the financial pressure mounts. The ‘picks and shovels’ logic—that selling infrastructure to miners is a safe bet—works only as long as the miners keep digging. When they stop, the shovel sellers suffer too.

    Revenue Concentration and Fragility

    The AI ecosystem is dangerously concentrated. A significant portion of AI revenue flows to a small number of infrastructure providers, especially Nvidia. If those companies’ spending slows, the entire ecosystem feels the shock. This fragility is a hallmark of bubbles. In the dot-com era, telecom companies overbuilt fiber-optic networks, expecting demand that never materialized. When the bubble burst, the overcapacity led to bankruptcies. AI’s infrastructure buildout—data centers, GPUs, energy contracts—is similar. The spending is already committed, but if demand softens, the overcapacity will be a burden.

    Enterprise Adoption Fatigue

    Despite the hype, many enterprises are struggling to see a return on their AI investments. Pilot projects often fail to scale, and AI tools see high churn rates. A recent survey found that most companies have not seen significant productivity gains from AI. This echoes the ‘productivity paradox’ of the 1980s and 1990s, when computers were everywhere but didn’t show up in economic statistics. The gap between promise and reality is causing a backlash. CFOs are asking tough questions about ROI, and budgets are being scrutinized. The era of ‘AI for AI’s sake’ is ending.

    Open-Source Competition and Price Compression

    Another factor deflating the bubble is the rise of open-source models. Llama, Mistral, and Qwen have shown that capable AI can be built and distributed freely. This compresses pricing power for commercial providers. Why pay for a proprietary model when a free one works almost as well? The result is a race to the bottom on price, squeezing margins. This is good for consumers but bad for startups that relied on high margins to justify their valuations. The open-source wave is a silent killer, eroding the moats that AI companies thought they had.

    The ‘We Don’t Know It Yet’ Factor

    So why haven’t we seen a crash? Because the bubble is deflating unevenly. The stock market is still propped up by a handful of mega-cap tech companies—Microsoft, Apple, Nvidia—that have diversified revenue streams. But beneath them, the AI sector is bleeding. Venture capital funding for AI startups has dropped, and many are taking down-rounds at lower valuations. The ‘we don’t know it yet’ framing is about the lag between reality and perception. By the time the headline indices reflect the correction, the damage will already be done.

    Historical Parallels: The Dot-Com Bubble

    The dot-com bubble of the late 1990s is the most instructive parallel. Then, as now, there was a belief that ‘this time is different.’ Companies with no earnings and no clear path to profitability were valued in the billions. The infrastructure buildout—fiber-optic networks, data centers—was massive. When the bubble burst, the NASDAQ fell 78% from its peak. Many companies went bankrupt, but the internet itself survived and thrived. The same will likely happen with AI. The technology is real and transformative, but the current valuations are not. A correction is inevitable, and it will be painful for those who overextended.

    The Road Ahead: A Correction, Not a Crash?

    Some argue that this is not a bubble but a correction—a necessary shakeout that will separate the wheat from the chaff. The AI sector will experience a de-rating of 30–50% off peak valuations, but not a systemic collapse. The technology will survive, and the winners will emerge stronger. This is the ‘trough of disillusionment’ in the Gartner Hype Cycle. It’s a normal part of the cycle, and it’s already happening in specific niches. Generative AI content tools, for example, have seen price wars and consolidation. The same is now spreading to enterprise AI and infrastructure.

    What Should You Do?

    For businesses and investors, the key is to be cautious. Don’t overpay for AI hype. Focus on fundamentals: revenue, profitability, and real-world use cases. For enterprises, don’t adopt AI just because it’s trendy. Ensure it delivers measurable ROI. For individuals, don’t panic. The AI revolution is real, but it will take time to mature. The bubble is popping, but that doesn’t mean AI is going away. It means the industry is growing up.

    Conclusion

    The AI bubble is popping, but we just don’t know it yet. The signs are all around us: overvaluation, high costs, revenue concentration, enterprise fatigue, and open-source competition. The correction is already underway, even if the headline indices haven’t caught up. But this is not the end of AI. It’s the end of the hype. The technology will survive, and the winners will be those who focus on sustainable value creation. As the bubble deflates, we have an opportunity to build a more realistic and resilient AI industry.

    The AI bubble is deflating, but this is not a death knell for the technology. It’s a necessary correction that will separate hype from reality. By understanding the signs—valuation gaps, cost pressures, and adoption fatigue—we can navigate the coming changes with clarity. The future of AI is bright, but it will be built on solid foundations, not speculative froth.

    Summary

    • The AI bubble is deflating slowly, not crashing, and the signs are already visible in layoffs, down-rounds, and quiet shutdowns.
    • Valuations for many AI companies far exceed their actual revenue, a classic bubble indicator.
    • The high costs of training and running AI models, combined with revenue concentration in a few infrastructure providers, create fragility.
    • Enterprise adoption is faltering as ROI fails to materialize, echoing the productivity paradox of earlier tech booms.
    • Open-source models are compressing pricing power, eroding the moats of commercial AI providers.

    FAQ

    Q: Is the AI bubble really popping?
    A: Yes, but it’s a slow leak, not a sudden burst. Many AI startups are facing layoffs, down-rounds, and closures, even though the stock market hasn’t fully reflected this yet.

    Q: What are the main signs of the bubble deflating?
    A: Key signs include overvaluation relative to revenue, high training and inference costs, revenue concentration in a few companies like Nvidia, enterprise adoption fatigue, and the rise of open-source models that undercut pricing.

    Q: Will AI technology survive the bubble?
    A: Absolutely. Like the internet after the dot-com crash, AI will continue to evolve and transform industries. The bubble is about valuations, not the technology itself.

    Q: What should businesses do in response?
    A: Focus on real-world use cases and measurable ROI. Avoid adopting AI just for hype. Be cautious with investments and prioritize fundamentals over speculation.

    Q: How long will the correction last?
    A: It’s hard to say, but historical parallels suggest a de-rating of 30–50% could occur over a few years. The industry will likely consolidate, and the strongest players will emerge.